Consensus: I hired five AIs to review my code (and they bicker)
It’s 2am. You just pushed a commit because “this was the last refactor, promise”. Who reviews that code? A human? They’re asleep. Now imagine a panel of five AIs getting on it right away, in parallel, arguing about it.
That’s exactly what Consensus does and this article tells you how.
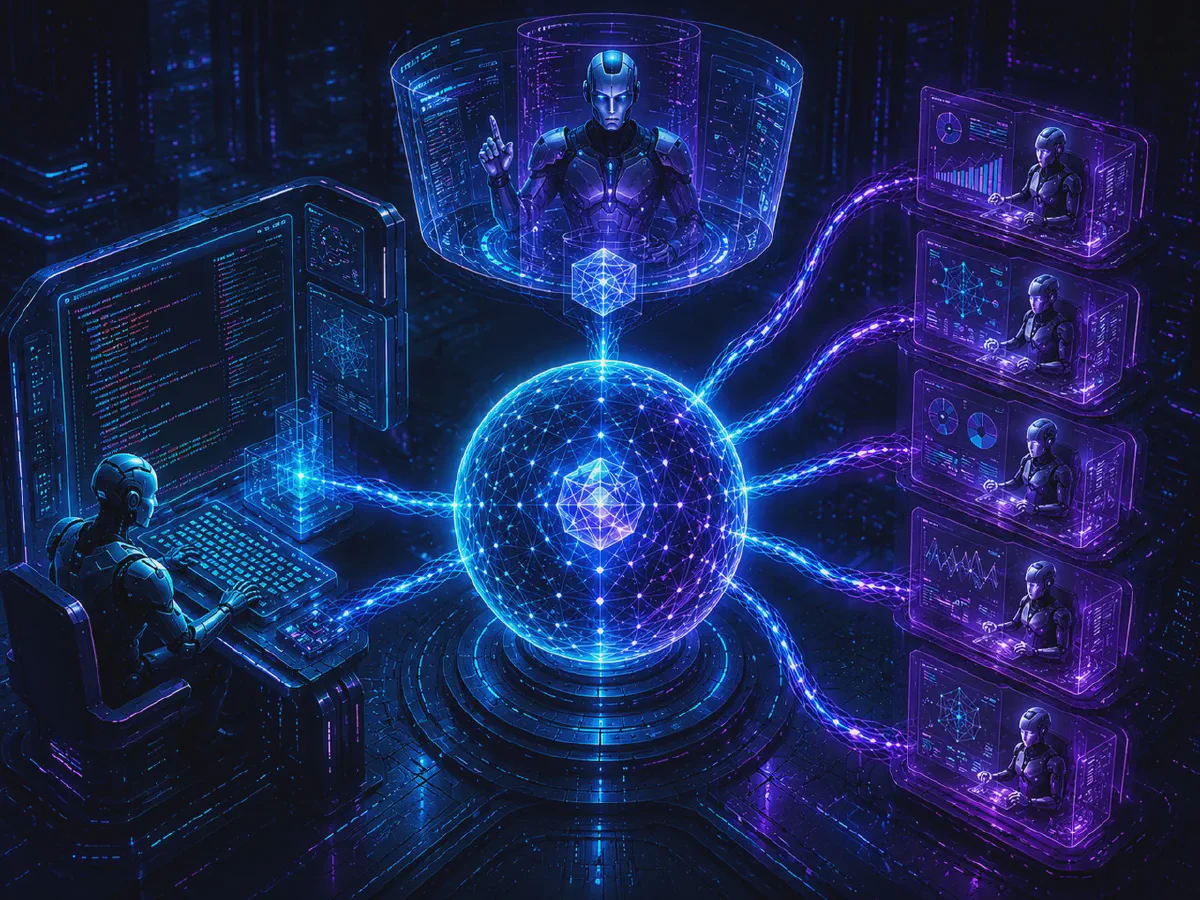
The cast
Four roles, like an office sitcom:
- coder: the hyperactive intern. Give it a spec, it spits out code. Fast, confident, occasionally exasperating.
- the panel: a handful of reviewers running in parallel. Each has its own model, personality and above all opinions.
- consensus: the accountant. Looks at who flagged what, computes an agreement score.
- lead: the boss. Reads everything, makes the call, signs off on the final code.
The whole flow fits on a sticky note:
spec -> coder -> panel (parallel) -> consensus -> lead
Everything is streamed to the browser over SSE: reviews land one by one, like flatmates coming home one after another to argue about the dishes.
No LangChain and we own it
The reflex would be to reach for an agent framework. Not here: two hand-written HTTP transports on httpx, one OpenAI-compatible and one Anthropic. Roughly 500 lines, every layer readable and when it breaks at 3am (there’s a theme here), you read the code, not a seven-level abstraction stack trace.
Accepted cost: reimplementing retry and streaming. Benefit: we know exactly what goes on the wire.
The club bouncer
Every call goes through the governor: the club bouncer. Per-provider rate limit (aiolimiter), retries (tenacity) and a fallback chain when a provider goes on strike.
My favorite detail: 429s and connection errors are retried by two layers, deliberately disjoint. Why? The HTTP layer is the only one that can read the Retry-After header. If both layers retried 429s, one failure would produce (N+1)^2 attempts. The code documents that trap in plain sight, because someone was going to do it one day.
If quota collapses, low-quota mode kicks in by itself: cheap models for the bulk work. But the lead is never downgraded. The boss keeps the good coffee; they’re the one signing.
There’s always a slow one in the group
Five reviewers in parallel, one always takes their sweet time (hello Opus). First idea: asyncio.gather, wait for everyone. Better idea: asyncio.as_completed: each review streams as it lands, no waiting for the last one in class.
Subtle side effect: counting tokens under that concurrency. Answer: contextvars, which propagate into tasks. One usage_scope() wraps the whole run and every call records itself, no list threaded through every function.
We NEVER trust the model (and we’re right)
The most important part of the project and the least glamorous: the consensus score is not what the model says it is. The model proposes flagged_by (who flagged what), the code checks:
- unknown names get rejected (a ghost reviewer? out),
- duplicates get deduped,
- the score is recomputed in Python:
round(min(len(flagged), n) / n, 3), mathematically clamped to 1.0.
An LLM is a hypothesis, the code is the truth. The kind of invariant that saves a project.
Consensus is not truth
And yet, the score recomputed in Python only solves part of the problem: it guarantees the agreement is correctly counted, not that the agreement is correct. The recent literature says it better than I do. The ailment of LLMs in code review is not so much what they miss as what they invent: plausible-but-wrong reports that overwhelm maintainers. The Refute-or-Promote paper (arXiv 2604.19049 ) quantifies the remedy with adversarial kill mandates and a mandatory empirical gate, killing 79 to 83% of candidates before disclosure. QASecClaw (arXiv 2605.01885 ) removes 88.6% of false positives (F1 90.93% vs 78.39% for Semgrep alone). The Tencent study (arXiv 2601.18844 ) eliminates 94-98% of false alarms at $0.0011-$0.12 per alarm, against 10-20 minutes of manual inspection. And single-pass tops out at an F1 of 19.38% (zylos ).
Multi-model helps without being enough: a single model family shares the same blind spots; it is the cross-family critic of Refute-or-Promote that catches what same-family misses. AgentAudit (dev.to ) goes further with weighted voting (quorum of 5, 60% threshold) and Sybil resistance. zylos documents the agreeableness bias: a model reviewing its own output inherits the biases that produced it, which justifies the panel of different models Consensus already deploys.
But the most chilling lesson comes from Refute-or-Promote: ten dedicated reviewers unanimously endorsed a Bleichenbacher oracle that did not exist in OpenSSL’s CMS module. Ten, unanimous, wrong. The thing was killed only by a single empirical test. That is the exact counterpoint to the project’s rule: consensus, even perfect, is not the truth, it is a test that decides.
So here is the reckoning. Consensus already does three things the literature recommends: the multi-model panel (against agreeableness bias), the score recomputed in code (never the model’s word) and distrust of the model. What it could add: an empirical gate, validate a finding with a test before accepting it; assumed cross-family diversity in the panel; structured findings with confidence and pass number to filter noise; and a provenance chain as an append-only log. The intern writes, the crew criticizes, the accountant counts, the boss signs. The test, still, remains to be written.
The torn-apart JSON, repaired, requested again
LLMs return JSON the way kids hand out birthday cards: crumpled. Three repair layers: json.loads, then raw_decode from the first { (goodbye markdown fences and prose), then json_repair as a last resort. Still failing? Ask again with a hint appended to the prompt and the lead raises max_tokens on every attempt, because truncation is the number one cause of torn JSON.
The run ALWAYS completes
Project rule: an execution always yields a result. A reviewer dies? Skipped. Consensus dies? The lead arbitrates on raw reviews. The lead dies? Degraded verdict, still carrying the intern’s code. The UI never shows an empty screen and that’s surprisingly harder than it sounds.
The generated code goes in a cage
Since the coder writes code that will be executed, the Docker sandbox applies the full security menu: --network none (no exfiltration), --read-only, --cap-drop ALL, no new privileges, process limit, a 64 MB noexec tmpfs as the only writable spot, a read-only workspace mount, timeout with kill. Generated code is an input, never a trusted guest.
Ping, ping, ping
Production detail: an Opus call can stay silent for 75 seconds and proxies take that as an invitation to kill the connection. Fix: an SSE heartbeat emitting ": ping" every 10 seconds when nothing happens. SSE comments are ignored by clients, proxies are soothed, everyone’s happy.
The numbers
- about 2,600 lines of orchestration (9 modules),
- 5 built-in providers, activated by their env key,
- about 301 tests, 100% offline,
- mutation testing (mutmut): tests hardened against mutants, not merely green,
- 4 teams declared in YAML: consensus, consensus-tested, pentest, sre.
Want another layer?
Adding a domain (a pentest team, an sre team…) = one teams/<name>.yaml file. Zero code. Skills, MCP tools, RAG and the sandbox are all declared in the manifest.
There you go. The intern writes, the crew criticizes, the accountant counts, the boss signs. And you finally get some sleep.